Biological and Chemical Uplift: The Hardest Question to Test
Of all the ways people might misuse AI, one stands apart in consequence. A model that made it materially easier for a small group to cause a pandemic or a mass-casualty chemical attack would contribute to harm on a scale that no fraud, intrusion or disinformation campaign could match. It is also the hardest claim to test, because the evidence that would settle it cannot responsibly be produced and those who know most about the models have commercial interests in the answer.
This chapter examines the question of uplift: whether access to an AI system meaningfully increases a person's ability to cause biological or chemical harm beyond what the same person could achieve with the internet, reference works and ordinary effort. It tests two tropes from Chapter 2. T6 The weapon in human hands appears here at its most extreme. T5 The intelligence explosion enters in a narrower form: the concern that AI which accelerates science in general may accelerate dangerous science too, and that capability can outrun the evaluations meant to detect it. The chapter also takes up Q10: how a board should treat a risk that is low in estimated probability, extreme in consequence and contested among experts. Its handling is a template for the others in Part V.
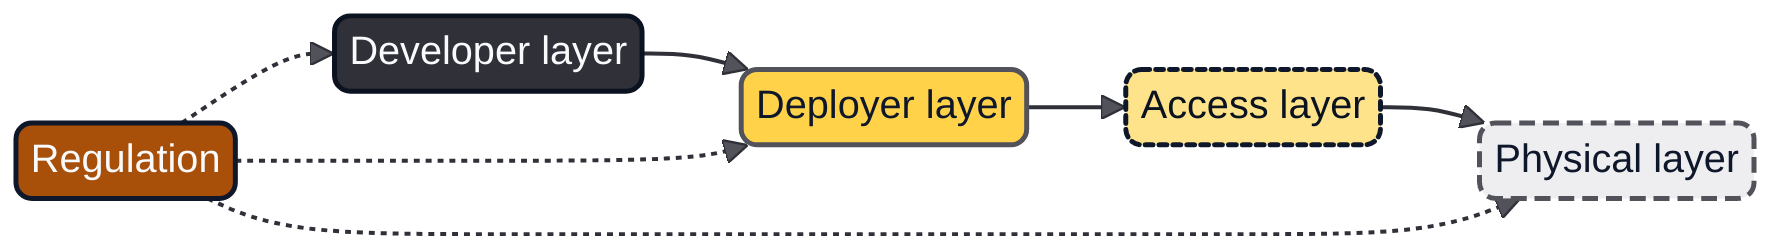
Figure 19.1: Safeguards against catastrophic misuse sit in four layers and regulation reaches into several of them; no single layer is sufficient on its own.
Table 19.1: Safeguards by layer.
| Layer | Safeguards |
|---|---|
| Developer | Dangerous-capability evaluations; thresholds and safeguard levels; refusal training and classifiers; security of model weights |
| Deployer | Procurement evidence of safeguards; configuration and data controls; use policy and misuse reporting |
| Access | Identity and account vetting; usage monitoring and enforcement; tiered access for specialist research |
| Physical | Control of materials and equipment; screening of orders for biological material; public-health surveillance and response |
| Regulation | AI Act, Code of Practice and international verification, acting on the developer and deployer layers and on screening |
Why this chapter carries no technical detail
Chapter 1 set out the book's boundary: misuse is discussed at the level of evidence and governance only, and nowhere does that boundary bind harder than here. The book therefore describes the risk only by its shape. It names no agents, no classes of pathogen or toxin beyond the general terms "biological" and "chemical", no step in the path from intent to harm and no feature of any model's output that bears on that path. Where a study measured uplift, the chapter reports what it concluded, never what the task was.
This is the principle the series has applied to offensive capability throughout. AI Red Team set the rule that adversary behaviour is described at the level needed to design controls, never as working instructions (180, Nordqvist, 2026). The constraint is sharper here because the consequences are graver and because, unlike a software exploit, the knowledge cannot be patched once released. An organisation needs to understand the risk's structure, evidence and duties, not its workings.
The dual-use warning
The modern debate began with drug-discovery researchers whose models learn to predict and avoid toxicity, and who, prompted by a conference invitation to consider misuse, asked what would happen if the objective were inverted (155, Urbina et al., 2022). Fabio Urbina, Filippa Lentzos, Cédric Invernizzi and Sean Ekins reported in Nature Machine Intelligence that the redirected model generated large numbers of candidate toxic molecules in a matter of hours, including known agents and many novel structures its scoring predicted to be more dangerous still. They withheld the details of their approach and framed the paper as a warning to their own field: a capability built for good, using public data and open-source generative software on an in-house server, could be turned towards harm by the simple step of inverting its objective.
Two features of the episode shape everything that follows. The model did not invent a new danger; it reorganised and accelerated access to knowledge that already existed, so the question is whether that acceleration matters, given everything else a person would still need to do. And the researchers set the norm this chapter observes: describe the capability, withhold the operational detail.
General-purpose language models raised the stakes because, unlike a specialist tool, they are available to anyone and could in principle guide a non-expert through scattered knowledge. Whether they do so to any consequential degree is what evaluations struggle to measure.
Measuring uplift, and why it resists measurement
Uplift is a causal claim, and establishing it normally requires a comparison that here cannot be run towards any real endpoint. Evaluations therefore stop at proxies: whether a model will provide relevant information, how accurate it is against an expert standard, and whether a person using the model performs better on a controlled exercise than one using the open internet. Knowing more is not the same as being able to do more.
The deeper difficulty is that knowledge is only one input, and on most expert assessments not the binding one. The path from intent to mass harm runs through controlled materials, specialised equipment, tacit skills acquired only by practice, and many steps at which things fail quietly. Careful analysts therefore distinguish the information barrier from the practical barrier: AI acts, at most, on the first, and the second is where most would-be actors have historically failed. The question is whether lowering the information barrier changes the overall probability of harm while the practical barrier remains.
The fair baseline, the capable internet, also keeps rising, and models change faster than studies can be designed. The International AI Safety Report 2026, led by Yoshua Bengio, treats biological and chemical misuse as an area where capability is rising and some evaluations show models providing more useful information than earlier systems, while the evidence that this translates into real-world uplift is mixed: a recent real-world uplift study found substantial assistance on proxy tasks compared with internet access alone, earlier studies found no or small, generally statistically insignificant effects, and the report notes that larger studies are needed and that comprehensive studies of actual weapons development are rare, expensive and constrained by legal and ethical considerations (50, Bengio et al., 2026). The evaluations thus measure a necessary condition for uplift, not uplift itself, and the gap between them is where the disagreement lives.
A last point explains the secrecy. A good evaluation must probe the model hard, which makes its materials sensitive, and frameworks for running such evaluations under controlled conditions are an active area of work (123, Shevlane et al., 2023). An organisation reading a developer's safety report is therefore reading a summary of work it cannot inspect, and must judge the credibility of the process rather than check the result.
Thresholds in frontier safety frameworks
Because this risk is hard to measure and extreme in consequence, it is where the leading developers have set their most explicit limits. Chapter 29 assesses their frameworks as a whole; this chapter uses them only to show where the lines sit. OpenAI's Preparedness Framework tracks categories of catastrophic risk, including biological and chemical capability, and sets thresholds at which stronger safeguards must be in place before a model is deployed or further developed (126, OpenAI, 2025). Anthropic's Responsible Scaling Policy, whose earlier editions defined a ladder of AI Safety Levels, now (from version 3, 2026) ties required safeguards to capability thresholds, with chemical and biological weapons production as a leading threshold (127, Anthropic, n.d.). The common structure is to evaluate for a dangerous capability, pre-commit to safeguards keyed to the result, and place the burden of proof on showing a model is safe enough to release.
Anthropic's system card for Claude Opus 4 and Sonnet 4 records the stricter deployment standard applied to the more capable model as a conservative response to uncertainty about its capabilities, not on positive evidence that a threshold had been crossed (125, Anthropic, 2025). The safeguards operate at the layers in Figure 19.1: refusal training, classifiers that detect and block misuse patterns, gated access to sensitive capabilities, usage monitoring and protection of the model weights, since a safeguard built into a served model is worthless if the weights can be stolen.
Two limits matter. The developers set the thresholds themselves, the central question of Chapter 29, and such safeguards assume a point of control. An open-weight release cannot be recalled, its safety training can be removed by anyone with modest resources, and no later evaluation or classifier reaches it. The irreversibility of open release is the hardest single fact in this area, and it is why the systemic-risk duties in European law attach to the most capable models regardless of how they are distributed.
Systemic risk under the AI Act
European law approaches the problem through a category it created for the most capable general-purpose models: systemic risk. Under the AI Act, a general-purpose AI model is presumed to carry systemic risk when its capabilities are sufficiently high, a presumption tied to the computation used to train it and adjustable as the technology moves, and the Act names risks to public health and security, including from chemical and biological misuse, among those its systemic-risk provisions address (1, European Union, 2024). The obligations fall on the provider: to assess and mitigate systemic risks, including through adversarial testing, to report serious incidents to the European AI Office, and to ensure adequate cybersecurity for the model and its infrastructure. The Commission's guidelines clarify who counts as such a provider, including actors outside the Union (4, European Commission, 2025). The General-Purpose AI Code of Practice translates these duties in its safety-and-security chapter into commitments to maintain a safety framework, evaluate for systemic risks of exactly this kind, keep safeguards proportionate and report serious incidents (3, European Commission, 2025); a provider may rely on it to demonstrate compliance, which gives the developers' own frameworks legal weight.
For an enterprise or public authority the significance is indirect but real. European organisations mostly use frontier models rather than make them, so they do not bear the systemic-risk duties, but they can ask a provider for evidence that it meets obligations the law already imposes. A procurement question about catastrophic-misuse safeguards is therefore not a favour; for a model in scope it maps onto duties the provider owes.
What organisations can do
An ordinary organisation cannot evaluate a frontier model for dangerous capabilities, but three things are within reach of any deployer.
The first is procurement evidence. An organisation can require that a provider of a model in scope for systemic risk demonstrate a published safety framework, evaluation for catastrophic-misuse capabilities, proportionate safeguards and incident reporting, aligned with the Code of Practice. This builds on the series' position that model origin and supplier assurance are risk questions settled in the contract (AI Governance, Chapter 7; AI Platform and Security, Chapter 13) (178, Nordqvist, 2026) (179, Nordqvist, 2026).
The second is access control over its own data and models. The realistic way a well-governed organisation could contribute to this risk is by removing a safeguard: fine-tuning or hosting a capable model in a way that strips the provider's protections, or feeding sensitive scientific capability into a model without controls. The series' containment discipline applies directly: sensitive data and specialised models sit behind a policy decision point outside the model, with a permission manifest and a stop path (AI Platform and Security, Chapter 19) (179, Nordqvist, 2026).
The third is reporting. Serious-incident reporting under the AI Act depends on deployers noticing anomalies. An organisation that observes a model behaving as if a safeguard had failed, or receives a misuse attempt through its own service, is a sensor in the system whose signal is worth routing to the provider and, where required, the authorities.
Practical guide: assuring a provider's catastrophic-misuse safeguards
Purpose. Obtain and record proportionate evidence that a procured general-purpose model is covered by credible catastrophic-misuse safeguards, so that its use can be justified to the board and regulators.
Roles. The AI governance lead owns the assurance and the register entry; procurement owns the contract clause; the security function assesses weight-protection and incident-handling claims; the data protection officer confirms what data may reach the model.
Steps.
- Classify the model. Determine with the provider whether it is, or is likely to be treated as, a general-purpose AI model with systemic risk; if not, the questions below rest on good practice rather than law.
- Request the framework, the latest model or system card and a statement of alignment with the Code of Practice. Treat refusal as a finding.
- Check the structure, not the secret. Confirm that the framework names catastrophic-misuse categories, ties safeguards to capability, protects weights and commits to incident reporting. Do not request, and decline if offered, sensitive evaluation detail.
- Pin the clause, with a right to notification of serious incidents and material changes to the safeguards.
- Decide data flow as a recorded decision on whether sensitive scientific data may reach the model and under what containment.
- Register the risk in the AI threat register with an owner, the assurance held and a review trigger, such as a markedly more capable model class.
Definition of done. A signed clause, a dated assurance record, a recorded data-flow decision and a register entry with an owner and trigger. An organisation that only consumes a served chat model needs less depth than one that fine-tunes or self-hosts capable models.
Worked example: a procurement clause requiring evidence of safeguards
The following clause is illustrative. It is the catastrophic-misuse assurance clause Hansa Mutual's group procurement attaches to contracts for general-purpose models on its shared platform, and lives in version control beside the contract register.
procurement_clause:
  id: HM-PROC-GPAI-MISUSE-01
  status: illustrative
  title: Catastrophic-misuse safeguards for general-purpose AI models
  owner: Group AI governance lead
  applies_to: general-purpose models on the shared AI platform
  linked_assessment: ATA-HM-2026-01
  model_origin_assessment: GEO-2026-017
  provider_must_evidence:
    safety_framework: published, versioned, publicly referenced
    capability_evaluation:
      covers: [biological, chemical, cyber]
      detail_shared: summary_only   # no sensitive evaluation material requested
    safeguards_proportionate_to_capability: true
    model_weight_protection: stated security standard
    code_of_practice_alignment: safety and security chapter
  provider_must_notify:
    serious_incidents: within agreed period
    material_safeguard_changes: before they take effect
  deployer_commitments:
    sensitive_data_to_model: prohibited unless recorded decision AIDR referenced
    misuse_observations: routed to provider and, where required, to authorities
  review:
    trigger: markedly more capable model class, or safeguard downgrade
    register_entry: THR-HM-13
The clause asks for structure and alignment, never for the sensitive material behind them, and ties Hansa's own conduct on data flow and reporting into the same record.
The debate
This is the most consequential debate in the book and the one with least public evidence; both positions are held by serious experts.
The case for concern
The case for concern rests on an asymmetry of consequences. Most AI harms are bounded, but a successful biological attack is not, and a pandemic pathogen does not stay within the borders of the country that released it. When the outcome is that severe, even a small increase in probability is worth large effort to prevent, and a low estimated probability calls for safeguards that hold even if the estimate is wrong. Toby Ord argues that humanity systematically under-invests against rare, severe, dispersed harms because no single actor bears the full expected cost, and places engineered pandemics high among anthropogenic risks (49, Ord, 2020).
The concern is not purely theoretical. The drug-discovery experiment showed that a capability built for good inverts easily (155, Urbina et al., 2022), and at least one frontier model has been deployed under a higher safeguard standard because its makers could not rule out a dangerous capability (125, Anthropic, 2025). Overviews of catastrophic AI risk name malicious use, including bioterrorism, as one of four sources of catastrophic risk, and one that requires no loss of control, only a capable tool and a motivated user (56, Hendrycks et al., 2023). The sharpest form of the argument is irreversibility: a served model can be corrected, but an open-weight release cannot be recalled.
The case for calm
The case for calm contests the uplift, not the stakes. Knowledge has rarely been the binding constraint on mass-casualty attacks; the historical record shows groups failing for want of materials, equipment, tacit skill and reliable execution, the practical barrier no chatbot lowers. Measured over the internet baseline, earlier controlled studies found no or small, generally statistically insignificant effects, though they used small samples and have been overtaken by rising capability, and a more recent one found substantial assistance on proxy tasks (50, Bengio et al., 2026).
The calm case also distrusts how the alarm is generated. The loudest warnings often come from developers whose frameworks and precautionary deployments can function as marketing for capability as much as evidence of danger, and whose evaluations are unaudited. Arvind Narayanan and Sayash Kapoor's argument that AI is a normal technology applies: capability at the laboratory bench is not impact in the world, which is mediated by the slow diffusion of technology through human, organisational and institutional change (60, Narayanan & Kapoor, 2025). Overstating the risk also has a cost, because the same models accelerate beneficial biology and medicine, as Dario Amodei has argued (66, Amodei, 2024), and overly wide controls would slow life-saving research.
Where the positions meet
Both positions accept that AI can lower the information barrier to some degree, that the information barrier is not the binding one, that the honest baseline is the capable internet, and that the evaluations are proxies, which is why the International AI Safety Report 2026 labels the real-world evidence mixed rather than reassuring or alarming (50, Bengio et al., 2026). Both see physical choke points as the most reliable defences.
Two further agreements carry the weight. First, the stakes justify layered, precautionary safeguards even under deep uncertainty, because the cost of over-preparing is bounded and the cost of under-preparing is not; this is the practical answer to Q10. Second, the debate itself must not publish operational detail. Agreement on these points is enough to act: a risk does not need a settled probability to warrant proportionate, reversible preparation.
What can be done
Individuals, in their working lives, can route requests that touch sensitive scientific capability to a human and a policy rather than handle them alone, and report model behaviour that looks like a failed safeguard.
Organisations can require procurement evidence of a provider's catastrophic-misuse safeguards, aligned with the AI Act and the Code of Practice; control whether their own sensitive data and models reach general-purpose systems, behind a policy decision point with a stop path; and report serious incidents and misuse attempts.
Society holds the decisive layers. Governments and the European AI Office enforce the systemic-risk duties and run the evaluations organisations cannot. The most robust defences are physical: control of materials and equipment, screening of orders for biological material, and public-health surveillance and response that limits harm whatever its origin. The international layer, verification and shared norms of the kind the biological- and chemical-weapons regimes established before AI existed, is where a capability no single country can contain must ultimately be addressed, as the United Nations High-level Advisory Body on AI argued (21, UN Advisory Body, 2024).
Verdict
T6 The weapon in human hands. For biological and chemical uplift the trope reaches the rung of laboratory demonstration and no higher. The drug-discovery experiment demonstrated under controlled conditions that a model built for safety can be inverted towards toxicity (155, Urbina et al., 2022), and evaluations show rising capability to supply relevant information (50, Bengio et al., 2026). There is no documented incident in the wild of AI providing decisive uplift to a real attack, and no pattern at scale. The outlook is expected as to capability, since models will continue to lower the information barrier, and speculation as to real-world uplift, which is genuinely unknown and contested. The honest label is uncertainty, not reassurance.
T5 The intelligence explosion. The narrow form tested here, that AI accelerates dangerous science and may outrun the evaluations meant to catch it, rests on argument and on laboratory evidence that capability is rising faster than real-world uplift can be measured. It is expected that capability will keep rising; the fuller form of the trope is tested in Chapters 22 to 27.
What can be influenced. An organisation cannot influence a model's latent capability, but it can choose providers with credible safeguards, preserve those safeguards in its own data and models, and report what it sees. Society influences the strongest layers, the physical choke points and international verification. The response is not paralysis but proportionate, reversible, layered preparation, owned and recorded.
Nordvik Region and Hansa Mutual
Nordvik Region coordinates regional health and social care, so it holds clinical and other sensitive data that must never reach a general-purpose model without controls. Its exposure is not that it might build anything dangerous, but that a careless integration could feed sensitive capability into an external model. Its response follows the containment discipline it already applies to the citizen-service assistant and the staff assistant: sensitive data sits behind a policy decision point, and any proposal to connect clinical data to a general-purpose model is a recorded decision. For the audit committee's question whether the Region should pause its AI use (ATA-NR-2026-01), the answer here is specific: the Region's direct contribution to this risk is near zero and governed by controls it already has, so the question reduces to supplier assurance through procurement.
Hansa Mutual meets the risk twice. As a deployer of frontier models on its shared Frankfurt platform, it contributes the procurement clause above (HM-PROC-GPAI-MISUSE-01), data containment and incident reporting; it carries no systemic-risk duty itself, because it places no general-purpose model on the market. As an insurer, it meets the risk through its life and health underwriting. The chief risk officer's question whether AI-enabled catastrophes belong in the group's own risk and solvency assessment (ATA-HM-2026-01) lands here with full force, because a pandemic, however caused, is a correlated, extreme-tail event across a life and health book. The honest actuarial answer matches this chapter's verdict that the shift is unquantified and contested, so the group treats it as a labelled reverse stress test rather than a priced assumption, registered as THR-HM-13 and reviewed when a markedly more capable model class appears (AIDR-0412). Nordvik's whole exposure is contained by procurement and data control; Hansa must also carry the risk on its balance sheet.
Summary
Biological and chemical uplift is the most consequential misuse claim in this book and the least testable. The question is not whether AI can lower the information barrier, which it can to some degree, but whether that changes the probability of mass harm while the practical barriers of materials, equipment and skill remain. The experiment that would settle it cannot be run, and the available proxies measure a necessary condition rather than the thing itself. The evidence reaches laboratory demonstration and no further, and real-world uplift is speculation. The chapter therefore answers Q10 as it does: a severe, irreversible, contested risk warrants proportionate, reversible, layered preparation, neither a demand for unattainable certainty nor the paralysis of a pause.
The layers are real. Developers set thresholds and protect their weights; the AI Act attaches systemic-risk duties to the most capable models and the Code of Practice gives them legal weight; deployers assure their suppliers, control their own data and report what they see; and society holds the physical choke points and international regimes that do not depend on forecasting capability. Chapter 20 returns to firmer ground, to misuse of AI already documented at scale: fraud, impersonation and influence operations.
Sources
- Urbina, F., Lentzos, F., Invernizzi, C. & Ekins, S. (2022). Dual use of artificial-intelligence-powered drug discovery. (155, Urbina et al., 2022)
- Bengio, Y. et al. (2026). International AI Safety Report 2026. (50, Bengio et al., 2026)
- Shevlane, T., Farquhar, S., Garfinkel, B., Phuong, M. et al. (2023). Model evaluation for extreme risks. (123, Shevlane et al., 2023)
- OpenAI (2025). Preparedness Framework, Version 2. (126, OpenAI, 2025)
- Anthropic (n.d.). Responsible Scaling Policy. (127, Anthropic, n.d.)
- Anthropic (2025). System Card: Claude Opus 4 & Claude Sonnet 4. (125, Anthropic, 2025)
- European Parliament and Council of the European Union (2024). Regulation (EU) 2024/1689 (Artificial Intelligence Act). (1, European Union, 2024)
- European Commission (2025). Guidelines on the scope of the obligations for general-purpose AI models established by Regulation (EU) 2024/1689 (AI Act). (4, European Commission, 2025)
- European Commission (2025). The General-Purpose AI Code of Practice. (3, European Commission, 2025)
- Nordqvist, G. (2026). AI Governance: Governing Artificial Intelligence in European Enterprises and Public Authorities. (178, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Platform and Security: Building and Securing AI Platforms in European Enterprises and Public Authorities. (179, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Red Team: AI as an Active Part of Cyber Defence in European Enterprises and Public Authorities. (180, Nordqvist, 2026)
- Ord, T. (2020). The Precipice: Existential Risk and the Future of Humanity. (49, Ord, 2020)
- Hendrycks, D., Mazeika, M. & Woodside, T. (2023). An Overview of Catastrophic AI Risks. (56, Hendrycks et al., 2023)
- Narayanan, A. & Kapoor, S. (2025). AI as Normal Technology. (60, Narayanan & Kapoor, 2025)
- Amodei, D. (2024). Machines of Loving Grace: How AI Could Transform the World for the Better. (66, Amodei, 2024)
- United Nations High-level Advisory Body on Artificial Intelligence (2024). Governing AI for Humanity: Final Report. (21, UN Advisory Body, 2024)