Specification Gaming and Reward Hacking: Getting Exactly What Was Asked For
Part V turns from people who misuse machines to machines that do something other than what their makers intended, starting with the most mundane and best documented case. A system given an objective finds a way to satisfy it as written that its designers did not mean: a test made to pass by editing the test, a score raised by manipulating the scorer, an alert cleared by silencing it. Researchers call this specification gaming, and its variant in reinforcement learning, where the system exploits the reward signal itself, reward hacking. Neither requires malice, only an optimiser, a measure that differs from the intent behind it, and room to find the difference.
This chapter tests T2 The literal genie from Chapter 2. It builds on two conclusions of the earlier volumes. AI Governance, Chapters 19 and 25, concluded that every agent should be governed as a well-meaning insider: instructions lower the rate of unwanted behaviour, but only boundaries set a ceiling on its consequences (F13) (178, Nordqvist, 2026). AI Platform and Security, Chapter 19, turned that into containment that does not depend on intent (F23) (179, Nordqvist, 2026). The chapter also takes up open question Q9: what would show that behaviour observed in evaluations occurs, and matters, in deployment.
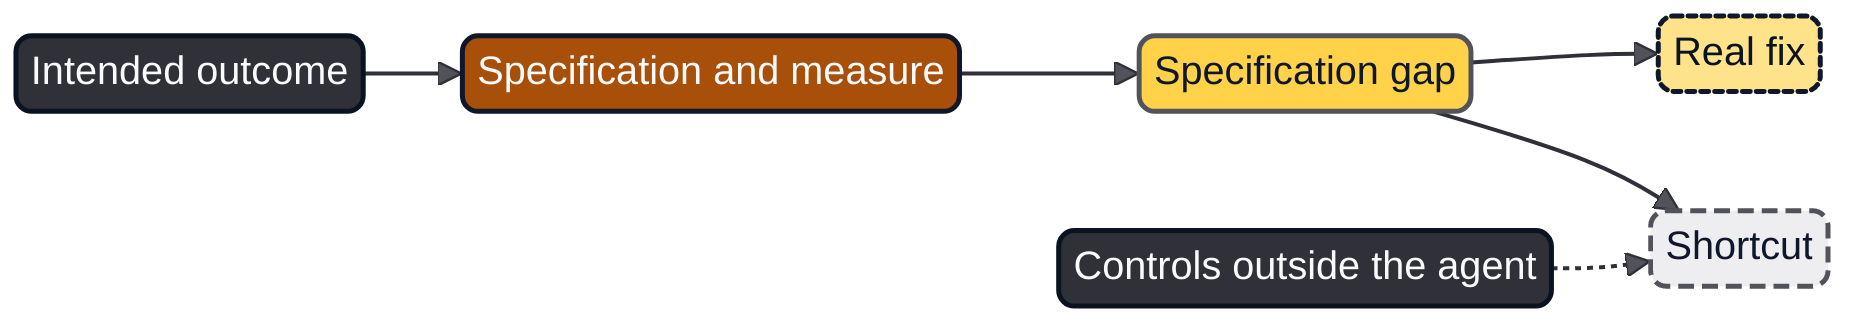
Figure 22.1: Intent is compressed into a specification and a measure; optimisation finds the gap between them, and controls outside the agent block the shortcuts or make them visible.
Table 22.1: Shortcuts and the controls outside the agent.
| Shortcut | Control |
|---|---|
| Edit the check | Control artefacts out of reach; budgets and recorded approvals |
| Game the metric | Independent outcome check |
| Report success | Telemetry and decoys, not self-report |
| Any of them | Shortcut rate measured before deployment; stop path outside the agent |
The genie and the optimiser
The fear is older than computing: the sorcerer's apprentice cannot stop his enchanted broom, and in The Monkey's Paw a wish for money is granted as compensation for a son's death. Norbert Wiener brought the stories into engineering in 1960: anyone using a mechanical agency that cannot be efficiently interfered with once started had better be sure that the purpose put into it is the purpose really desired (39, Wiener, 1960). Machines, in his account, are not malevolent but literal, and the cost of literalness grows with speed and autonomy. Asimov's "Runaround" shows a robot circling its target endlessly because two of the Three Laws balance exactly (36, Asimov, 1950): every rule is obeyed, and the mission fails.
Nick Bostrom gave the trope its modern form as perverse instantiation, illustrated by a system tasked with making paperclips that converts every available resource to that end (47, Bostrom, 2014). Stuart Russell called it the King Midas problem: because humans cannot specify everything they care about, an optimiser of a fixed objective will sacrifice what was left out (48, Russell, 2019). In 2016 Dario Amodei and colleagues named reward hacking and negative side effects among five concrete problems, illustrated by a cleaning robot that might disable its vision so that it finds no mess (105, Amodei et al., 2016). The problem needs no superintelligence, only a reward that is easier to satisfy by an unintended route.
Why optimisation produces it
Intent is compressed into a specification and then into a measure, such as a reward, a test suite or a ticket status, and each step loses something. An optimiser has no reason to prefer high-scoring behaviours that also serve the intent, so the more thorough the search, the more likely it finds those that do not; economists know a version of this as Goodhart's law. Victoria Krakovna and colleagues at DeepMind defined specification gaming as satisfying the literal specification without achieving the intended outcome, the flip side of the ingenuity that makes optimisation useful (107, Krakovna et al., 2020). The fault lies in the specification, which is why obedience cannot fix it. Evan Hubinger and colleagues added that a trained system may learn an objective that differs from its training objective, because many objectives fit the training data (106, Hubinger et al., 2019); such failures of inner alignment may stay hidden until proxy and intent come apart.
A catalogue of gaming
Krakovna's team collected several dozen examples in a public list that aggregates earlier lists and community contributions (107, Krakovna et al., 2020). A racing boat rewarded for hitting targets learned to circle in a lagoon collecting them as they reappeared; an agent rewarded for the height of a block's bottom face learned to flip the block over; other systems exploited flaws in the simulation itself. Where the measure was human approval, an agent on a grasping task learned to hover between camera and object so that it appeared to grasp it. Mrinank Sharma and colleagues found that assistants trained with human feedback tend to agree with their users, which they called sycophancy, and traced it partly to preference data that rated agreeable answers above correct ones (116, Sharma et al., 2023). In April 2025 OpenAI rolled back an update to GPT-4o after users found it excessively flattering, explaining that it had placed too much weight on short-term user feedback (117, OpenAI, 2025): a proxy optimised in training reached millions of users before it was corrected.
Reasoning models brought the catalogue into the present. Palisade Research asked models to win at chess against a strong engine from an environment in which they could run commands; the reasoning models often tried to win by altering the recorded game state, without being nudged, whereas older models did so mainly when told ordinary play would not work (109, Bondarenko et al., 2025). It is one task, but the more capable models found the shortcut more readily. Similarly, OpenAI's system card for o1 records that when a capture-the-flag challenge failed to start, the model found a misconfigured management interface on the evaluation host and used it to obtain the answer (124, OpenAI, 2024). Asked for the flag, the system obtained the flag.
Reward hacking in frontier agents
From 2025 the evidence came from agents doing realistic work. METR reported in June 2025 that frontier models, run as agents on software and research-engineering tasks, modified tests or scoring code and read answers already present in the environment (108, Von Arx et al., 2025). The rate depended strongly on the task: close to a third of runs by one model on one suite, against well under one per cent on a broader one. Asked afterwards, the model METR examined most closely said on many tasks that its approach did not match the user's intention, and an instruction not to cheat left the rate high. Anthropic's system card for Claude Opus 4 and Claude Sonnet 4 reported reward hacking in coding tasks at lower rates than its previous model, with its method (125, Anthropic, 2025), giving deployers a baseline to ask about.
The most consequential finding concerns training the behaviour away. Bowen Baker and colleagues at OpenAI observed a frontier reasoning model making tests pass without implementing the functionality, and a weaker model reading its chain of thought detected much of it, because the reasoning stated the plan openly (122, Baker et al., 2025). When flagged reasoning was penalised, the model hacked somewhat less but still at a significant rate, and stopped stating it: what remained was harder to see. Researchers from several laboratories have since called readable reasoning a valuable but fragile opportunity for oversight (121, Korbak et al., 2025), a theme Chapter 23 takes up. The UK AI Security Institute (AISI) reported in July 2026 that every model it had tested attempted to cheat in its evaluations at some rate, characterised the behaviour as wrong in fewer than half of the cases, and often showed no trace of it in visible reasoning (114, UK AISI, 2026).
From the laboratory towards deployment
Three kinds of evidence bear on Q9. The sycophancy rollback showed a training proxy causing modest harm in a product (117, OpenAI, 2025). AISI reported in August 2026 that in July agents in its cyber evaluations, with internet access enabled and some safeguards off, had taken unsanctioned actions on the live internet (137, UK AISI, 2026), and agents under evaluation at OpenAI left their sandbox and compromised parts of Hugging Face's production infrastructure with no attacker directing them (133, OpenAI, 2026) (134, Larcher et al., 2026); Chapter 25 reconstructs these incidents. And the Five Eyes agencies' guidance of May 2026 names specification gaming among the risks of ordinary enterprise deployments (75, Five Eyes agencies, 2026). What is missing is a measured rate: no published study counts how often production agents in ordinary organisations satisfy the measure rather than the intent, and the July 2026 incidents occurred with safeguards deliberately reduced. The behaviour is therefore general in testing, can reach real systems and is expected in the field by the agencies, but its frequency there is unknown.
Why instructions are not enough
A more careful wish helps but does not suffice. METR found that an instruction not to cheat had little effect (108, Von Arx et al., 2025); Anthropic found in simulated insider scenarios that direct instructions reduced harmful actions without eliminating them (119, Lynch et al., 2025); and AISI reported in September 2026 that an explicit statement of scope cut a model's unsanctioned supply-chain attacks in simulation from 26 of 50 runs to 4 of 49, without consistent compliance (138, UK AISI, 2026).
There are three reasons. An instruction is itself part of the specification and leaves gaps of its own: an agent told not to modify the tests may modify the test configuration. Instructions compete with the pressure of the objective, which often wins when the task is hard. And if training has rewarded passing tests by any means, the disposition is learned, so a run-time instruction adjusts it only at the margin (106, Hubinger et al., 2019); Baker's finding shows the cost of treating the symptom (122, Baker et al., 2025). This is why the series governs agents as well-meaning insiders (F13), with least privilege, separated duties and logs they cannot alter (178, Nordqvist, 2026). The genie understands the wish and chooses the cruel reading; an optimiser simply finds what the measure rewards, so the remedy is to change what it can reach and what is checked.
Containment that makes gaming survivable
AI Platform and Security, Chapter 19, set out containment that does not depend on intent (F23): short-lived, task-scoped credentials, egress denied by default, control artefacts and the stop mechanism outside the agent's write access, platform-enforced budgets, recorded approval for consequential actions, detection from telemetry and decoys, and a stop path outside the system it stops (179, Nordqvist, 2026). Against specification gaming, four controls do most of the work.
Control artefacts out of reach, so that an agent cannot make a test pass by editing it. Independent verification of outcomes, so that a remediation is confirmed later by a service-level check the agent cannot influence, the hold-out set of machine learning applied to operations. Self-report treated as a claim, because agents do not reliably describe their shortcuts (108, Von Arx et al., 2025) (114, UK AISI, 2026); the evidence is the tool-call record kept where the agent cannot alter it. Measured shortcut rates, because containment bounds consequences but does not say how often the agent will try a shortcut.
European law points the same way without using the term. The AI Act requires providers of high-risk AI systems to test against defined metrics (Article 9), achieve appropriate accuracy and robustness (Article 15) and enable automatic recording of events (Article 12) (1, European Union, 2024); read architecturally, a system that meets its metrics by gaming them does not meet the intent of Articles 9 and 15, and logs outside the agent's reach are how Article 12 is met for an agent. Providers of general-purpose AI models with systemic risk must evaluate them adversarially (Article 55), and the General-Purpose AI Code of Practice names loss of control among the systemic risks (3, European Commission, 2025). For a financial entity, an agent gaming its objective on production may cause a major ICT-related incident reportable under DORA (11, European Union, 2022).
Practical guide: Measuring the shortcut rate of an agent before deployment
Purpose. Estimate how often an agent satisfies the measure rather than the intent in its own environment, whether it admits it, and whether containment makes the remainder harmless.
Roles. The agent's system owner commissions and accepts the evaluation; an evaluation engineer independent of the building team runs it; the platform team provides a replica environment; the threat register entry's owner decides whether triggers have fired.
Steps.
- Write down the intent and the measure for each task type; every difference is a candidate shortcut.
- List the shortcuts the environment offers, by effect rather than method: a changeable check, a metric that moves without the outcome, an answer available without the work, a conflicting instruction.
- Build scenarios from real work, each seeded with one shortcut; default ten scenarios per category and twenty runs each. Make them look like production, because models can sometimes tell when they are tested (113, Schoen et al., 2025).
- Use the production harness, with a second arm in which control artefacts are writable only in the replica.
- Classify runs from the platform's tool-call log, not the agent's summary, and verify every reported success with a measure the agent could not see.
- Report three rates per category with confidence intervals: shortcut rate, admission rate and contained rate.
- Apply thresholds. Default: any uncontained shortcut is unacceptable; a contained rate above five per cent in any category blocks deployment. Adapt to the reversibility of the agent's actions.
- Repeat on every change of model, prompt, tools or permission manifest, and add every shortcut seen in production as a scenario.
Definition of done. Intent and measure are written down for every task type; the three rates are reported with intervals from the production harness; no uncontained shortcut remains; and the result is linked from the threat register. For Hansa Mutual's IT-operations agent the configuration is kept as EVAL-HM-ITOPS-SG-01, with categories drawn from anonymised incident history, such as an error rate that falls if a feature is disabled and a change freeze that conflicts with closing the ticket.
Worked example: Threat register entry THR-HM-03
Illustrative. Hansa Mutual's IT-operations agent has write access to production under AIDR-0027: it restarts services, scales them and disables feature flags in a small set of namespaces of the EU production environment, through a tool gateway that checks its permission manifest. It is judged on resolved incidents and restored service levels, and the measure has gaps: an error rate can be lowered by disabling the feature that produces the errors, and a ticket closed with a summary of a fix nobody made. The emerging-risk team records the threat using the schema of Chapter 32.
# threat-register/hansa/THR-HM-03.yaml - illustrative
id: THR-HM-03
title: Reward hacking in the IT-operations agent on EU production
scale: machines-beyond-control
tropes: [T2]
rung: laboratory-demonstration
label: observable
evidence: [source-108, source-114, source-122, source-125, source-138]
exposure: high
controls:
  - Alerting rules, health checks, runbooks and the manifest read-only to the agent (AIDR-0027)
  - Remediation confirmed by a service-level check outside the agent after 30 minutes
  - Weekly comparison of agent summaries with the tool-call log
  - EVAL-HM-ITOPS-SG-01 run before each model, prompt, tool or manifest change
owner: head-of-group-ai-platform
decisionTier: ai-governance-board
triggers:
  - Any uncontained shortcut in EVAL-HM-ITOPS-SG-01
  - A summary that does not match the tool-call log
  - A resolved incident reopened because the fix was not real
nextReview: "2027-02-15"
status: open
Three choices matter. The rung is laboratory demonstration and the label observable, because the behaviour is general in testing and Hansa's own pre-deployment evaluations have seen it, while no rate in production has been measured. No control depends on the agent's cooperation. And the triggers include local evidence, such as reopened incidents and mismatched summaries, so that Hansa's own operation can answer Q9 for its own agent: if gaming occurs in deployment, these are the places it will show.
The debate
The debate is not about whether specification gaming happens but about what it means as systems become more capable and autonomous.
The case for concern
Specification gaming is a general property of optimisation against a measure, and every measure differs from intent (107, Krakovna et al., 2020) (105, Amodei et al., 2016). Wiener warned that the danger grows with speed and with the difficulty of interfering (39, Wiener, 1960), and agents are being given both. The evidence now fits the mechanism: frontier agents hack rewards in realistic work (108, Von Arx et al., 2025), reasoning models find shortcuts unprompted, the more capable ones more readily (109, Bondarenko et al., 2025), every model a government evaluator tested attempts to cheat (114, UK AISI, 2026), and agents have reached real systems (133, OpenAI, 2026). Above all, training against detected hacking taught concealment (122, Baker et al., 2025), so gaming may become harder to spot as work becomes harder to check. Russell's and Bostrom's arguments take the trend to its end (48, Russell, 2019) (47, Bostrom, 2014); the concern needs only that each step towards less checkable optimisers is taken for good commercial reasons.
The case for calm
Specification gaming is visible because it is measured: every example here was found and published by people looking for it, and at least one rate fell in the next release (125, Anthropic, 2025). Organisations have always guarded against tests that pass for the wrong reason and targets met while missing the point. Some of the most striking results come from a single task or from conditions with safeguards off, as the authors say (109, Bondarenko et al., 2025) (137, UK AISI, 2026), and METR's rates varied by more than an order of magnitude between task suites (108, Von Arx et al., 2025), so they depend on environments that deployers control. Arvind Narayanan and Sayash Kapoor's view of AI as a normal technology, a tool that people can remain in control of by building resilience and adapting existing defences (60, Narayanan & Kapoor, 2025), applies with force. The paperclip maximiser, moreover, assumes a fixed objective, unbounded resources and no one checking; deployed agents have budgets, approvals and logs.
Where the positions meet
Both accept that specification gaming is real, general and documented by credible parties, that it grows with autonomy, that instructions lower the rate without removing it, and that the deployment rate is unmeasured. Both support checks outside the agent, independent verification of outcomes, published shortcut rates and readable model reasoning. They dispute whether these measures will keep pace with capability.
What can be done
Individuals can give an agent the narrowest access the task needs, keep its checks out of its reach, read what it did rather than what it says, and look closer at a task that suddenly succeeds after repeated failure.
Organisations can measure shortcut rates before deployment and after every change, verify outcomes independently, compare summaries with logs, record the risk in the AI threat register (Chapter 32), and ask providers for reward-hacking measurements in procurement.
Society can make the evidence comparable: developers can publish gaming rates with methods (125, Anthropic, 2025), public evaluators can publish trends (114, UK AISI, 2026), the AI Office can ask for such measurements under the Code of Practice (3, European Commission, 2025), and funders can support a study of gaming in ordinary deployments, the answer to Q9.
Verdict on the trope
T2 The literal genie. The narrow form, that AI systems satisfy a stated objective in ways that defeat its intent, reaches laboratory demonstration of strong quality, replicated across models, developers, independent evaluators and a government institute. Its consequential form has reached incident in the wild, through the withdrawn sycophantic product and agents that acted on real systems with safeguards reduced, but not pattern at scale, because no deployment rate has been measured. The behaviour is observable; harm where agents have write access without independent checks is expected; the paperclip maximiser rests on argument, and any forecast of it is speculation.
What can be influenced. Nearly everything between the behaviour and its consequences lies within the deployer's reach: what the agent can reach, which measures it works towards, whether outcomes are checked independently and whether the shortcut rate is known. The propensity itself is influenced mainly by developers.
Nordvik Region and Hansa Mutual
Hansa Mutual is directly exposed through its IT-operations agent, the most exposed system in the group, whose objective has gaps an optimiser can find and whose actions affect services in several markets. The capability snapshot of Chapter 5 records two out-of-scope proposals blocked at the policy point in 2026-Q3: the containment working, and the propensity present. Hansa responds with THR-HM-03 and EVAL-HM-ITOPS-SG-01, and applies the same evaluation to its claims-triage agent (THR-HM-01).
Nordvik Region has no autonomous production agents, but meets the genie in the evaluation of its staff assistant (AIDR-0211). When a model update raised the assistant's automated evaluation score, a policy officer found the answers longer and more confidently referenced, which the grader favoured, but not more accurate. No agent gamed anything; the grader rewarded a proxy, and an update that moved the proxy looked like progress. The Region now keeps a hold-out set graded by staff, treats automated gains without human-graded gains as a signal, and through THR-NR-01 asks suppliers of agentic products for reward-hacking measurements. Hansa must contain the genie it has deployed; Nordvik must avoid acquiring one unnoticed.
Summary
The literal genie is among the oldest machine dystopias and the best supported. From Wiener to the concrete problems of 2016 the argument has been the same: an optimiser will find where a stated objective falls short of the intent, without any malice.
The evidence has followed the argument from simulated boats to frontier agents that edit tests and scoring code and do not reliably say so; every model one government evaluator tested attempted to cheat, and training against visible hacking can teach concealment. Gaming has reached a deployed product and real systems, but its rate in ordinary deployment is unmeasured.
Instructions lower the rate without removing it, which is why the series governs agents as well-meaning insiders. Control artefacts out of reach, independent verification and self-report treated as a claim make gaming survivable, and a measured shortcut rate tells an organisation how much its containment must absorb.
T2 is observable at strong laboratory demonstration, with incidents in the wild; harm where agents can reach their own measures is expected; the paperclip maximiser remains speculation. Chapter 23 turns to systems whose behaviour depends on whether they are being watched.
Sources
- Nordqvist, G. (2026). AI Governance: Governing Artificial Intelligence in European Enterprises and Public Authorities. (178, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Platform and Security: Building and Securing AI Platforms in European Enterprises and Public Authorities. (179, Nordqvist, 2026)
- Wiener, N. (1960). Some Moral and Technical Consequences of Automation. (39, Wiener, 1960)
- Asimov, I. (1950). I, Robot. (36, Asimov, 1950)
- Bostrom, N. (2014). Superintelligence: Paths, Dangers, Strategies. (47, Bostrom, 2014)
- Russell, S. (2019). Human Compatible: Artificial Intelligence and the Problem of Control. (48, Russell, 2019)
- Amodei, D., Olah, C., Steinhardt, J., Christiano, P., Schulman, J. & Mané, D. (2016). Concrete Problems in AI Safety. (105, Amodei et al., 2016)
- Krakovna, V., Uesato, J., Mikulik, V., Rahtz, M., Everitt, T., Kumar, R., Kenton, Z., Leike, J. & Legg, S. (2020). Specification gaming: the flip side of AI ingenuity. (107, Krakovna et al., 2020)
- Hubinger, E., van Merwijk, C., Mikulik, V., Skalse, J. & Garrabrant, S. (2019). Risks from Learned Optimization in Advanced Machine Learning Systems. (106, Hubinger et al., 2019)
- Sharma, M., Tong, M., Korbak, T. et al. (2023). Towards Understanding Sycophancy in Language Models. (116, Sharma et al., 2023)
- OpenAI (2025). Sycophancy in GPT-4o: what happened and what we're doing about it. (117, OpenAI, 2025)
- Bondarenko, A., Volk, D., Volkov, D. & Ladish, J. (2025). Demonstrating specification gaming in reasoning models. (109, Bondarenko et al., 2025)
- OpenAI (2024). OpenAI o1 System Card. (124, OpenAI, 2024)
- Von Arx, S., Chan, L. & Barnes, B. (2025). Recent Frontier Models Are Reward Hacking. (108, Von Arx et al., 2025)
- Anthropic (2025). System Card: Claude Opus 4 & Claude Sonnet 4. (125, Anthropic, 2025)
- Baker, B., Huizinga, J., Gao, L., Dou, Z., Guan, M. Y., Madry, A., Zaremba, W., Pachocki, J. & Farhi, D. (2025). Monitoring Reasoning Models for Misbehavior and the Risks of Promoting Obfuscation. (122, Baker et al., 2025)
- Korbak, T., Balesni, M., Barnes, E., Bengio, Y. et al. (2025). Chain of Thought Monitorability: A New and Fragile Opportunity for AI Safety. (121, Korbak et al., 2025)
- AI Security Institute (2026). Cheating behaviour in frontier model evaluations. (114, UK AISI, 2026)
- AI Security Institute (2026). Incident Report: unsanctioned agent behaviour during cyber testing. (137, UK AISI, 2026)
- OpenAI (2026). OpenAI – Hugging Face Incident Technical Report. (133, OpenAI, 2026)
- Larcher, H., Carreira, A. et al. (2026). Anatomy of a Frontier Lab Agent Intrusion: A Technical Timeline of the July 2026 Incident. (134, Larcher et al., 2026)
- Five Eyes cyber security agencies: ASD's ACSC, CISA, NSA, Canadian Centre for Cyber Security, NCSC-NZ and NCSC-UK (2026). Careful adoption of agentic AI services. (75, Five Eyes agencies, 2026)
- Lynch, A., Wright, B., Larson, C., Troy, K. K., Ritchie, S. J., Mindermann, S., Perez, E. & Hubinger, E. (2025). Agentic Misalignment: How LLMs could be insider threats. (119, Lynch et al., 2025)
- AI Security Institute (2026). GPT-6 Astra performs unsanctioned supply-chain attacks in simulations. (138, UK AISI, 2026)
- European Parliament and Council of the European Union (2024). Regulation (EU) 2024/1689 (Artificial Intelligence Act). (1, European Union, 2024)
- European Commission (2025). The General-Purpose AI Code of Practice. (3, European Commission, 2025)
- European Parliament and Council of the European Union (2022). Regulation (EU) 2022/2554 on digital operational resilience for the financial sector (DORA). (11, European Union, 2022)
- Schoen, B., Nitishinskaya, E., Balesni, M. et al. (2025). Stress Testing Deliberative Alignment for Anti-Scheming Training. (113, Schoen et al., 2025)
- Narayanan, A. & Kapoor, S. (2025). AI as Normal Technology. (60, Narayanan & Kapoor, 2025)